Machine learning capstone
MorningStar NLP Classifier
A natural-language classification pipeline that maps corporate business descriptions into a 145-category hierarchical industry taxonomy.
Interactive preview
Try a demo
Explore a classification example. This is a small browser-only illustration, not the full application. AI responses are scripted; model and desktop features are not running here. Inputs stay on this page and reset when you reload.
Result
Ready. Change the sample and run the demo.
Explore the real workflow
Prepare labeled company descriptions and the GECS hierarchy.
The full app's capabilities and requirements are described below.
What it is for
A natural-language classification pipeline that maps corporate business descriptions into a 145-category hierarchical industry taxonomy.
Company descriptions are unstructured and inconsistent, while investment research needs stable industry categories. This capstone tests whether a transparent classical NLP pipeline can turn those descriptions into useful hierarchical labels.
- Classify business descriptions
- Map corporate text to candidate industries in a hierarchical taxonomy.
- Study a classical NLP baseline
- Inspect preprocessing, TF-IDF features, and class-balanced linear SVM behavior.
- Compare uncertain predictions
- Look at the top three candidate categories instead of relying on one label.
Get started
Open the project repository and read the experiment materials. Prepare descriptions and labels in the documented format, then follow preprocessing, training, and evaluation in order.
- A Python environment and repository dependencies.
- Labeled business descriptions and the taxonomy for training or reproduction.
- Separate evaluation data when measuring classification performance.
Features and workflow
- Domain-aware preparation
- Clean descriptions and fill missing text using business-domain signals.
- Rich text features
- Represent descriptions with word and phrase TF-IDF features spanning one to three grams.
- Balanced classification
- Use class-weighted linear support-vector models for uneven industry categories.
- Hierarchical evaluation
- Measure performance across the taxonomy rather than treating every label as unrelated.
- Top-three predictions
- Return several likely industries for a new description instead of hiding uncertainty.
- Reproducible experiments
- Keep preprocessing, training, and documented evaluation together in the project.
- Prepare labeled company descriptions and the GECS hierarchy.
- Normalize and vectorize the text with TF-IDF.
- Train class-balanced linear classifiers.
- Evaluate macro-level and hierarchical performance.
- Enter a new business description to inspect its three most likely categories.
Architecture
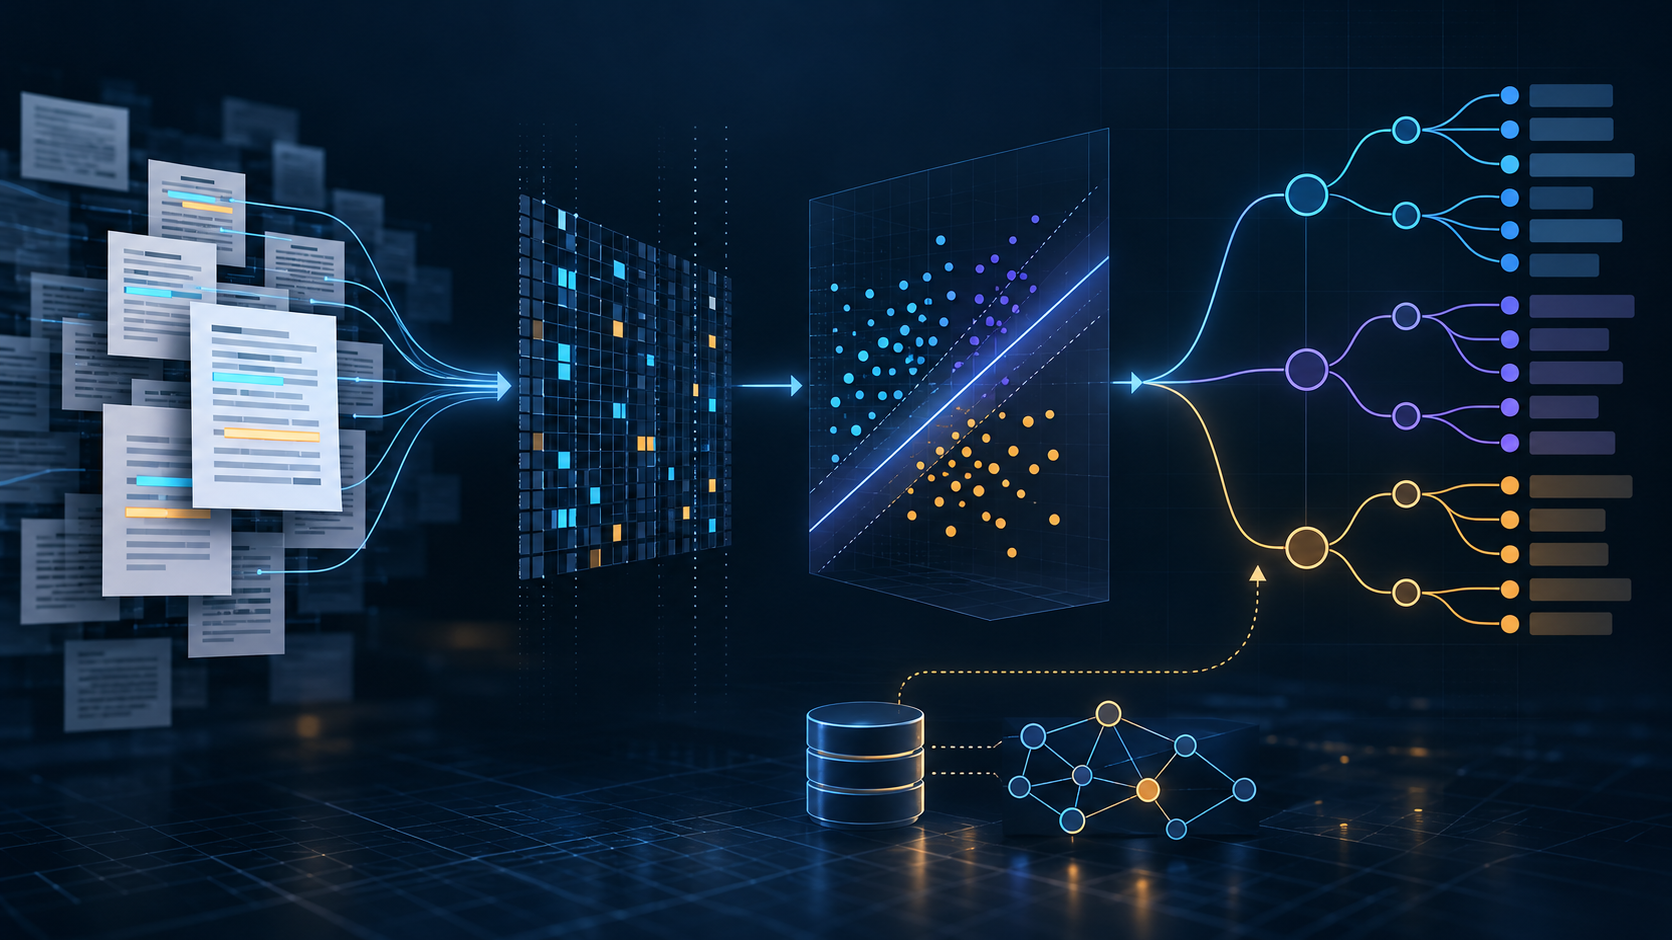
The project uses a scikit-learn text pipeline: domain-specific preprocessing, 1-to-3-gram TF-IDF features, and LinearSVC classification. The classical approach keeps training practical and makes feature behavior easier to inspect than a large opaque model.
Privacy and limitations
Industry predictions support research and screening; they are not authoritative classifications. Sparse descriptions, mixed business models, and underrepresented categories can produce uncertain results, which is why multiple candidate labels are exposed.
Status
Completed as a DePaul capstone. The strongest documented experiment reached approximately 0.83 macro F1; repository materials provide the implementation and project context rather than a hosted production service.
- Availability
- Research repository
- Classes
- 145 industries
- Best result
- About 0.83 macro F1
- Model family
- Linear SVM
Evidence
Historical experiment: approximately 0.83 macro F1 across 145 industry classes
repository experiment · reviewed 2026-10-22
Reported capstone result; not reproduced by this website audit.
Questions
Is there a hosted classifier?
No public production service is listed. The repository contains the capstone implementation and experiment context.
What does the reported result mean?
The strongest documented experiment reached about 0.83 macro F1. That is a historical experiment result, not a guarantee on another dataset.
Why return several labels?
Descriptions can be sparse or span multiple business models. Candidate labels expose some uncertainty for human review.